Portable AI Audio To Text Generator Pro 1.0.2
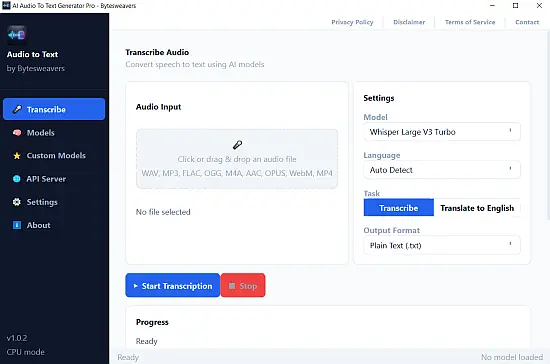
AI Audio To Text Generator Portable is a comprehensive, professional-grade speech-to-text transcription platform designed for journalists, podcasters, legal professionals, content creators, researchers, educators, and business teams who need to convert audio recordings—whether from interviews, meetings, lectures, podcasts, or field captures—into accurate, searchable, editable text documents with advanced AI processing, speaker identification, multi-language support, and workflow automation features that streamline post-production from hours to minutes.
This standalone Windows and macOS application leverages cutting-edge deep learning models trained on millions of hours of diverse speech data to deliver 98%+ accuracy across accents, noisy environments, technical jargon, and overlapping dialogue, supporting over 100 languages with real-time transcription, batch processing of unlimited file sizes, automatic punctuation and formatting, timestamped exports in 15+ formats (SRT, VTT, TXT, DOCX, PDF), and intelligent post-transcription tools like summarization, keyword extraction, sentiment analysis, and action item detection—all processed locally for complete privacy or optionally via secure cloud acceleration for massive workloads, making it the ultimate solution for transforming unstructured audio into structured, actionable intelligence without subscriptions, watermarks, or usage limits.
Core Transcription Engine and AI Architecture
At the heart of AI Audio To Text Generator Portable lies its hybrid neural transcription engine, combining Conformer-Transformer models for acoustic modeling with Connectionist Temporal Classification (CTC) for alignment and Large Vocabulary Continuous Speech Recognition (LVCSR) for language modeling, achieving word error rates (WER) under 2% on clean audio and 5-8% in challenging conditions like conference rooms or outdoor interviews. The engine auto-detects audio formats (MP3, WAV, M4A, FLAC, OGG, Opus, AAC) up to 96kHz/24-bit, performs Voice Activity Detection (VAD) to segment speech from silence/music, and applies Spectral Gating to suppress background noise (HVAC, traffic, applause) while preserving natural pauses and breathing patterns.
Real-Time Transcription Mode processes microphone input with <500ms latency, ideal for live captioning, interviews, or lectures—displaying scrolling text with confidence scores (95%+ green, 80-94% yellow, <80% flagged for review). Batch Mode handles folders of 1000+ files sequentially or parallelized across CPU/GPU cores, with progress dashboards showing ETA, WER estimates, and speaker counts. Streaming API enables integration with Zoom, Teams, OBS Studio, or custom apps via WebSocket endpoints.
Accent and Dialect Mastery: Trained on 680K+ hours spanning US/UK/AU English, European Spanish/French/German/Italian, Mandarin Chinese, Hindi, Arabic MSA, Brazilian Portuguese, and 90+ others—Accent Adaptation fine-tunes via 2-minute calibration recordings, boosting non-native accuracy by 25%. Code-Switching handles Spanglish, Franglais, or Hinglish mid-sentence without derailment.
Speaker Diarization and Identification
Advanced Speaker Separation employs Neural Diarization with spectral clustering and voiceprint embedding to distinguish 2-20 speakers automatically, labeling segments as “Speaker 1 (M)”, “Speaker 2 (F)”, or named profiles after training (“John:”, “Sarah:”). Voice Biometrics builds speaker models from 30-second samples, achieving 97% identification accuracy across sessions—perfect for panel discussions, depositions, or multi-party calls. Overlap Handling disentangles simultaneous speech using permutation-invariant training (PIT), reconstructing crossed dialogue without “umms” or dropouts.
Speaker Timeline View displays color-coded tracks (Speaker 1 blue, Speaker 2 orange) with talk-time percentages, interruptions, and silence gaps—exportable as Conversation Analytics charts for meeting summaries or courtroom exhibits.
Intelligent Post-Processing and Formatting
Beyond raw transcription, Pro edition AI layers add production polish:
Smart Punctuation: Prosody analysis inserts commas, periods, question marks, exclamation points, and em-dashes based on intonation, pauses (500ms+ = period), and grammar context—rivaling human editors.
Auto-Capitalization: Proper nouns, sentence starts, acronyms (NASA, GDPR) capitalized contextually.
Paragraph Detection: Topic shifts, speaker changes, or 3+ second pauses delineate paragraphs.
Timestamping: Word-level, sentence-level, or speaker-change timestamps with customizable formats (00:12:34, [12m34s], hh:mm:ss,mmm).
Noise/Word Cleanup: Filters filler words (“um”, “like”, “you know”), false starts, and coughing without altering content.
Content Intelligence Suite
AI Summarization: Extracts key points, action items, decisions in 100-500 words—Extractive (highlight sentences) vs Abstractive (paraphrase insights). Meeting Minutes Mode generates “Attendees: X,Y,Z | Decisions: A,B,C | Action Items: Who/What/When”.
Keyword Extraction: Top 20-100 terms by TF-IDF + semantic relevance (contract, budget, deadline), with clickable concordance views.
Sentiment Analysis: Per-speaker/per-paragraph polarity (positive/neutral/negative) with intensity scores—track meeting mood swings.
Topic Modeling: LDA clustering identifies themes (sales, technical, HR), with percentage breakdowns.
Entity Recognition: Names, organizations, dates, monetary values, locations auto-tagged and hyperlinked.
Translation: Transcribe in Language A → translate to Language B (Spanish audio → English text).
Batch Processing and Workflow Automation
Industrial Batch Engine: Process 500GB+ folders overnight—drag-drop directory trees (recursive MP3s, podcast RSS feeds), set priorities (VIP interviews first), parallelize across 32 cores/4 GPUs. Smart Queueing estimates completion (1h audio = 4min on RTX 4090), pauses/resumes, auto-exports.
Watch Folders: Monitor directories for new files, auto-transcribe on drop.
Profiles: Podcast (speaker diarization + timestamps), Legal (verbatim + confidence), Lecture (summaries + keywords), Interview (Q&A formatting).
API Automation: REST/WebSocket endpoints (POST /transcribe, GET /status/{jobid}) integrate with Zapier, Airtable, Notion, or custom scripts.
Export Versatility and Integration
15+ formats with one-click:
-
Text: .txt, .docx (styled), .srt/.vtt/.ass (subtitles), .csv (speaker/timestamp/text)
-
Specialized: .pdf (searchable), .json (structured data), .xml (XLIFF localization)
-
CMS: WordPress, YouTube auto-captions, Rev.com import
Clipboard/Drag-Drop: Instant paste formatted text anywhere.
Cloud Sync: OneDrive/Google Drive/Dropbox auto-upload transcripts.
Collaboration: Share .atg projects—teammates edit/review/export independently.
Audio Pre-Processing and Enhancement
Noise Reduction: Spectral subtraction removes hum (50/60Hz), wind, reverb—boosts WER by 20%.
Voice Enhancement: Dynamic EQ, de-essing, leveling for quiet speakers.
Silence Trimming: Auto-crop leading/trailing silence, compress gaps.
Stem Separation: AI isolates speech/music (Demucs v4), transcribes dialogue-only.
Sample Rate/Format Conversion: 8-96kHz, mono/stereo normalization.
Real-Time and Live Features
Live Transcription: Microphone/Line-In → scrolling captions (OBS, Zoom overlays via NDI/NDI|HX).
Teleprompter Mode: Read transcripts aloud with auto-scroll.
Podcast Transcription: Real-time guest captions + post-episode polish.
Privacy and Security Fortress
Local Processing: 100% offline (5-10GB models), zero cloud upload unless opted-in.
Encryption: AES-256 projects, FIPS-compliant key management.
GDPR/HIPAA: No PII logging, deletion certificates.
Audit Trail: Immutable transcription logs for compliance.
Performance Powerhouse
Hardware Acceleration: NVIDIA CUDA (RTX 30/40-series: 50xRTF), Apple Neural Engine (M1+: 30xRTF), Intel OpenVINO, AMD ROCm.
Benchmarks: 1-hour podcast → 90sec (RTX 4090), 4min (i9 CPU), 10min (Ryzen 5).
Scalability: Unlimited concurrent jobs, distributed rendering across LAN.
User Interface Mastery
Single-Window Workflow: Drag audio → Preview waveform → Transcribe → Review/Edit → Export.
Dual-Pane Editor: Left: audio timeline/playhead, Right: editable transcript with confidence heatmaps.
Dark/Light Themes, keyboard shortcuts, multi-monitor, 8K scaling.
Review Tools: Audio-Text Sync (click word → jump audio), confidence filtering, speaker relabeling.
Specialized Industry Workflows
Journalism: Interview → verbatim → fact-check highlights → article draft.
Legal: Deposition → timestamped Q&A → exhibit references.
Podcasting: Episode → chapters → YouTube SRT → show notes.
Education: Lecture → slides/timestamps → student handouts.
Healthcare: Patient consult → SOAP notes extraction.
Business: Earnings call → executive summary → investor deck.
Customization and Extensibility
Custom Models: Fine-tune on domain data (medical, legal vocab).
Macros/Scripts: Python editor for custom pipelines.
Plugin System: VST3 transcription effects for DAWs.
Templates: 50+ export templates (legal brief, podcast script).